
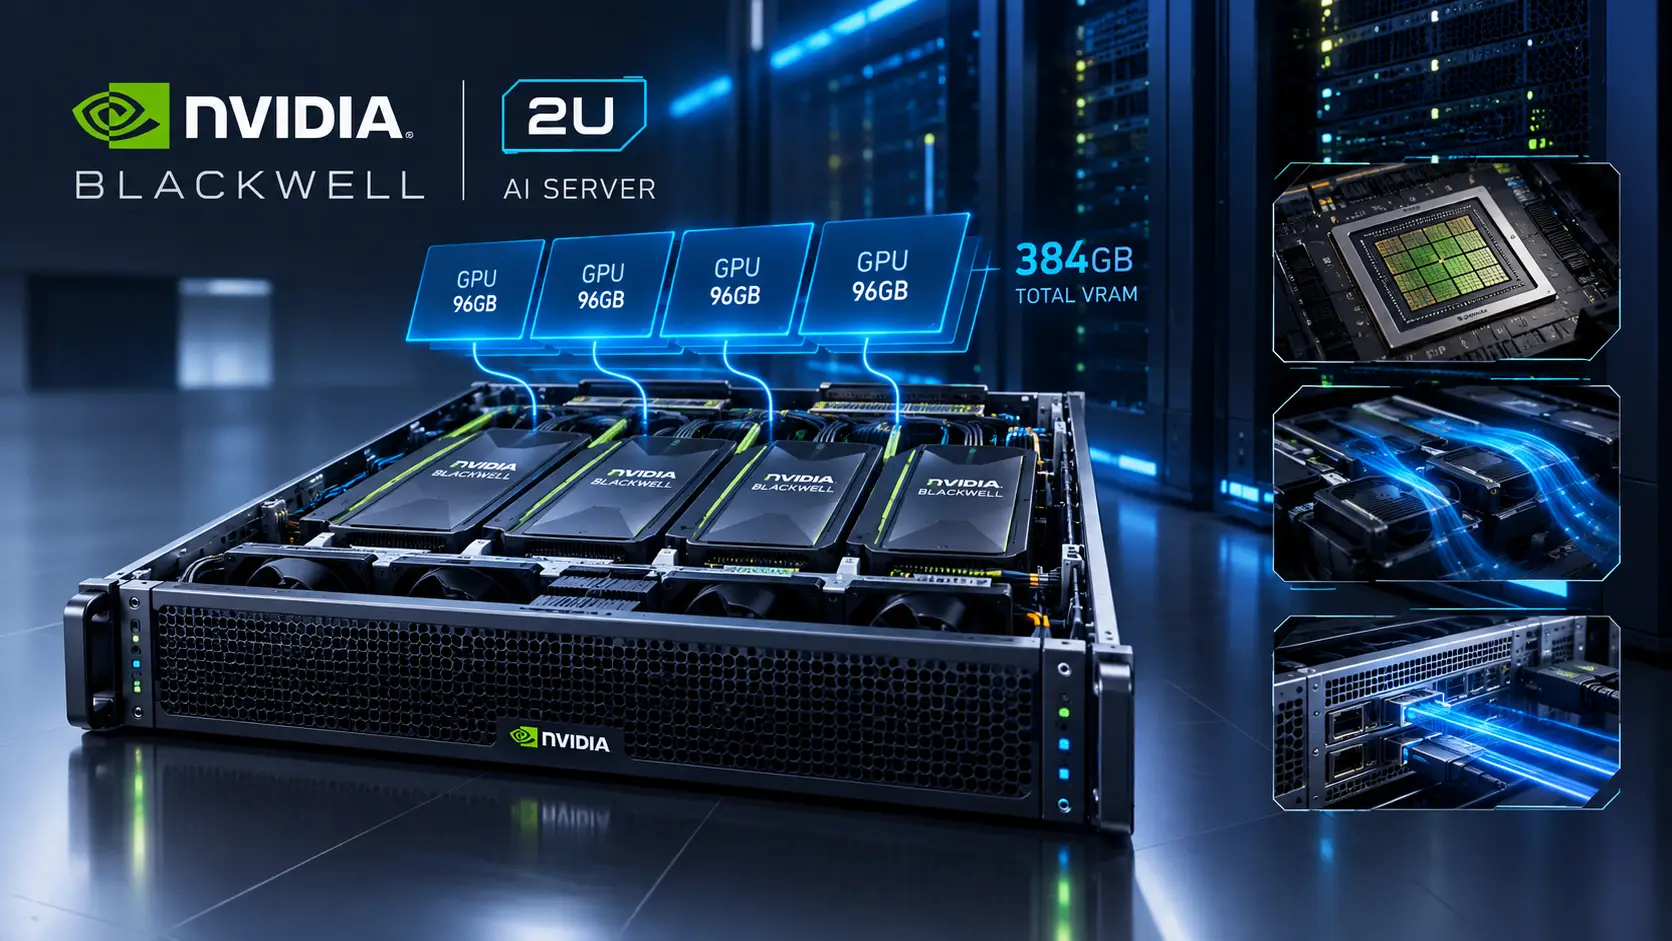
The artificial intelligence landscape has reached an inflection point where the size of Large Language Models (LLMs) and the physical constraints of data centers are in direct conflict. As parameters scale into the hundreds of billions, the demand for massive, unified memory pools (VRAM) has skyrocketed. However, global export controls, compliance regulations, and silicon availability have forced organizations to rethink how and where they host their AI infrastructure.
Instead of relying on multi-tenant cloud ecosystems, enterprises are shifting toward localized, dedicated hardware. Hosting providers like iDatam offer the physical foundation for this shift, enabling organizations to deploy custom, ultra-dense configurations. With the release of the Nvidia Blackwell architecture, it is now possible to house unprecedented computational power in a standard 2U rackmount chassis. This tutorial serves as your definitive guide to architecting, deploying, and managing these high-density servers.
What You'll Learn
Hardware Layouts & Thermodynamics in a 2U Chassis
OS Initialization and Driver Provisioning
Pooling 384GB VRAM for LLM Workloads
Securing Sovereign AI Environments
Continuous Benchmarking & Thermal Monitoring
Conclusion
Frequently Asked Questions (FAQ)
Section 1: Hardware Layouts & Thermodynamics in a 2U Chassis
When dealing with a 2U (3.5-inch height) server chassis, space is the ultimate premium. Traditional horizontal PCIe mounting limits the number of dual-slot GPUs you can install, typically maxing out at two before thermal or spatial boundaries are crossed.
To fit four Nvidia RTX Pro 6000 Blackwell Max-Q GPUs (each sporting 96GB of VRAM to reach the 384GB total), hardware engineers utilize custom riser cards that rotate the GPUs 90 degrees. This vertical orientation provides two critical advantages:
-
Maximized PCIe Lane Proximity: The risers connect directly to the dual CPU sockets, ensuring PCIe Gen 6x16 bandwidth is distributed evenly without latency-inducing multiplexer (PLX) chips.
-
Unobstructed Front-to-Back Airflow: High-TDP Blackwell chips generate immense heat. In a 90-degree layout, the server's front-mounted high-RPM counter-rotating fans push cold air in a straight, unimpeded line directly through the passive heatsinks of the GPUs and out the rear exhaust.
Power Considerations: A quad-Blackwell configuration easily draws over 2,000 watts under full load. Ensure your iDatam dedicated server is equipped with 2+2 redundant 3000W Platinum or Titanium-rated PSUs.
Section 2: OS Initialization and Driver Provisioning
-
Update the base system and install compilation tools on your fresh Ubuntu 24.04 LTS instance:
Bashsudo apt update && sudo apt upgrade -y sudo apt install -y build-essential dkms linux-headers-$(uname -r) curl wget git vim htop -
Install the Nvidia Blackwell Server Driver Stack:
Bashdistribution=$(. /etc/os-release;echo $ID$VERSION_ID | sed -e 's/\.//g') wget https://developer.download.nvidia.com/compute/cuda/repos/$distribution/x86_64/cuda-keyring_1.1-1_all.deb sudo dpkg -i cuda-keyring_1.1-1_all.deb sudo apt update # Install the headless Nvidia driver (adjust version to the latest Blackwell branch) sudo apt install -y nvidia-driver-550-server nvidia-dkms-550-server sudo reboot -
Install the CUDA Toolkit and Docker Environment:
Bashsudo apt install -y cuda-toolkit-12-4 echo 'export PATH=/usr/local/cuda/bin${PATH:+:${PATH}}' >> ~/.bashrc echo 'export LD_LIBRARY_PATH=/usr/local/cuda/lib64${LD_LIBRARY_PATH:+:${LD_LIBRARY_PATH}}' >> ~/.bashrc source ~/.bashrc curl -fsSL https://get.docker.com -o get-docker.sh sudo sh get-docker.sh sudo apt install -y nvidia-container-toolkit sudo nvidia-ctk runtime configure --runtime=docker sudo systemctl restart docker
Section 3: Pooling 384GB VRAM for LLM Workloads
Large Language Models (like Llama-3-70B) cannot fit into a single 96GB card during training. We must pool the memory. Ensure Nvidia Collective Communications Library (NCCL) is active via nvidia-smi nvlink -s.
Below is a foundational Python script demonstrating how to use PyTorch Fully Sharded Data Parallel (FSDP) to shard model parameters, gradients, and optimizer states across all four GPUs.
import os
import torch
import torch.distributed as dist
import torch.nn as nn
import torch.optim as optim
from torch.distributed.fsdp import FullyShardedDataParallel as FSDP

def setup_distributed(rank, world_size):
    os.environ['MASTER_ADDR'] = 'localhost'
    os.environ['MASTER_PORT'] = '12355'
    dist.init_process_group("nccl", rank=rank, world_size=world_size)
    torch.cuda.set_device(rank)

def train_model(rank, world_size):
    setup_distributed(rank, world_size)

    class MassiveModel(nn.Module):
        def __init__(self):
            super(MassiveModel, self).__init__()
            self.layers = nn.Sequential(*[nn.Linear(8192, 8192) for _ in range(24)])

        def forward(self, x):
            return self.layers(x)

    model = MassiveModel().to(rank)
    fsdp_model = FSDP(model) # Wraps model in FSDP to shard across 384GB pool

    optimizer = optim.Adam(fsdp_model.parameters(), lr=1e-4)
    criterion = nn.MSELoss()

    inputs = torch.randn(32, 8192).to(rank)
    targets = torch.randn(32, 8192).to(rank)

    fsdp_model.train()
    for epoch in range(5):
        optimizer.zero_grad()
        outputs = fsdp_model(inputs)
        loss = criterion(outputs, targets)
        loss.backward()
        optimizer.step()

    dist.destroy_process_group()

if __name__ == "__main__":
    WORLD_SIZE = torch.cuda.device_count()
    torch.multiprocessing.spawn(train_model, args=(WORLD_SIZE,), nprocs=WORLD_SIZE, join=True)
Section 4: Securing Sovereign AI Environments
-
Implement air-gapped network policies using UFW to restrict traffic strictly to internal management subnets:
Bashsudo ufw default deny incoming sudo ufw default deny outgoing # Allow internal SSH access sudo ufw allow in from 10.50.0.0/16 to any port 22 # Allow outbound traffic ONLY to specific internal registry sudo ufw allow out to 10.50.10.100 port 443 # Allow local loopback (critical for multi-GPU NCCL communication) sudo ufw allow in on lo sudo ufw allow out on lo sudo ufw enable -
Isolate inference workloads (like vLLM) in Docker using internal networks:
YAMLversion: '3.8' services: vllm-inference: image: vllm/vllm-openai:latest deploy: resources: reservations: devices: - driver: nvidia count: all capabilities: [gpu] volumes: - /mnt/secure_models:/models command: --model /models/Llama-3-70B --tensor-parallel-size 4 networks: - ai-backend-net ports: - "127.0.0.1:8000:8000" # Bound ONLY to localhost networks: ai-backend-net: internal: true # Prevents reaching the internet
Section 5: Continuous Benchmarking & Thermal Monitoring
A 2U chassis housing four Blackwell GPUs operates on the edge of thermal physics. We must implement a continuous monitoring daemon to log telemetry data.
-
Create the monitoring bash script at
/usr/local/bin/gpu-monitor.sh:Bash#!/bin/bash LOG_FILE="/var/log/gpu_monitor.log" TEMP_THRESHOLD=85 while true; do GPU_DATA=$(nvidia-smi --query-gpu=index,name,temperature.gpu,power.draw --format=csv,noheader,nounits) while IFS=',' read -r index name temp power; do temp=$(echo $temp | xargs) if [ "$temp" -ge "$TEMP_THRESHOLD" ]; then echo "$(date): CRITICAL: GPU $index reached ${temp}C!" >> $LOG_FILE fi done <<< "$GPU_DATA" sleep 5 doneMake it executable:
sudo chmod +x /usr/local/bin/gpu-monitor.sh -
Create a Systemd service to run it continuously:
INI[Unit] Description=Nvidia GPU Thermal Monitoring Daemon After=network.target [Service] Type=simple ExecStart=/usr/local/bin/gpu-monitor.sh Restart=always User=root [Install] WantedBy=multi-user.targetEnable and start the service:
sudo systemctl enable --now gpu-monitor.service
Conclusion
Architecting a high-density 2U AI server is a complex convergence of hardware engineering, software optimization, and rigorous security management. By deploying up to four Nvidia RTX Pro 6000 Blackwell Max-Q GPUs within an iDatam dedicated server, organizations bypass the bottlenecks of public clouds and the restrictions of global hardware quotas.
With 384 GB of unified VRAM successfully pooled via NVLink and PyTorch FSDP, your infrastructure is primed to handle the largest foundational models securely.
Frequently Asked Questions (FAQ)
Why rotate the GPUs 90 degrees in a 2U chassis?
Rotating the GPUs allows up to four dual-slot high-performance cards to fit side-by-side in a 2U rack. This vertical orientation significantly improves thermal management by aligning the GPU heatsinks directly with the server's high-velocity front-to-back airflow, preventing thermal throttling.
Can I run a 70B parameter LLM on this iDatam setup?
Yes. A 70B parameter model typically requires around 140GB of VRAM just to load at 16-bit precision, and well over 250GB for efficient training and optimizer states. The combined 384GB VRAM pool in this quad-GPU architecture handles this effortlessly without resorting to performance-degrading quantization.
How does PyTorch FSDP differ from standard DataParallel?
Standard DataParallel copies the entire model onto each individual GPU, which is impossible if the model is larger than a single GPU's capacity. Fully Sharded Data Parallel (FSDP) fragments the model layers across the total available VRAM (384GB), allowing you to train massive models cooperatively.
What is Sovereign AI, and why does it require dedicated servers?
Sovereign AI refers to artificial intelligence systems built, trained, and hosted locally to maintain strict data privacy, intellectual property ownership, and compliance with regional laws. Dedicated bare-metal servers, like those provided by iDatam, ensure no other tenant shares your hardware, preventing data leaks.
What happens if a Blackwell GPU hits its thermal limit?
If a GPU exceeds its maximum safe operating temperature (usually around 85°C to 90°C), it will aggressively downclock its core frequencies (thermal throttling) to shed heat. This dramatically slows down your training job, which is why a custom thermal monitoring daemon is crucial.
iDatam Recommended Tutorials

Control Panel
How to Fix Invalid cPanel License Error?
Find out how to fix the Invalid cPanel License error with this step-by-step guide. Resolve licensing issues quickly and get your hosting control panel back on track.


Control Panel
How to Install and Use JetBackup in cPanel
Learn how to install and use JetBackup in cPanel with this step-by-step tutorial. Discover how to back up and restore accounts, files, databases, and more efficiently.

Network
Remote Desktop Can’t Connect To The Remote Computer [Solved]
Learn how to fix the Remote Desktop can't connect to the remote computer error. Discover common causes such as network problems, Windows updates, and firewall restrictions, along with step-by-step solutions to resolve the issue and restore your remote desktop connection.
Discover iDatam Dedicated Server Locations
iDatam servers are available around the world, providing diverse options for hosting websites. Each region offers unique advantages, making it easier to choose a location that best suits your specific hosting needs.
